bedrock
-
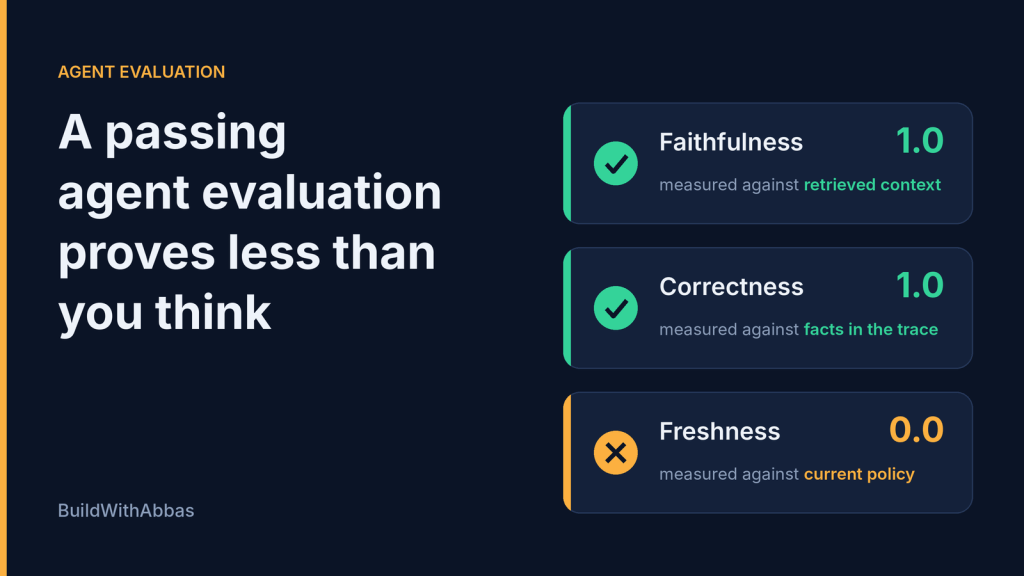
A passing agent evaluation proves less than you think
A grounded, plausible answer scored 1.0 twice and was still wrong. Six questions to ask before you trust any agent evaluation score, drawn from…
-
HTTP 200, Wrong Answer: Testing Agent Evaluations with CloudWatch Omni
A stale policy produced a grounded but wrong answer—and two passing AgentCore scores. A real CloudWatch Omni lab tests what an independent freshness check…
-

MCP in Production: Designing the Tool Layer for Enterprise AI Agents on AWS
MCP makes it easier for AI agents to interact with tools, but enterprise production systems require much more than a protocol. This architecture deep…

