ai
-
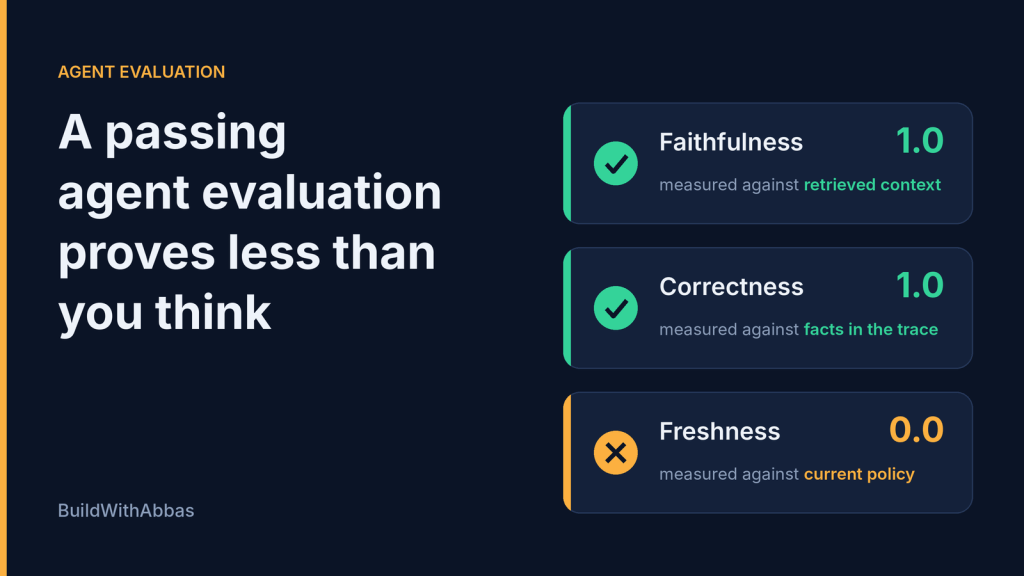
A passing agent evaluation proves less than you think
A grounded, plausible answer scored 1.0 twice and was still wrong. Six questions to ask before you trust any agent evaluation score, drawn from…
-
HTTP 200, Wrong Answer: Testing Agent Evaluations with CloudWatch Omni
A stale policy produced a grounded but wrong answer—and two passing AgentCore scores. A real CloudWatch Omni lab tests what an independent freshness check…
-
Your replica copied the bad DELETE. Now recover the orders that came next.
Recover an analytical orders table after a bad DELETE using S3 Tables snapshots, retained source events and a validated cutover.
-
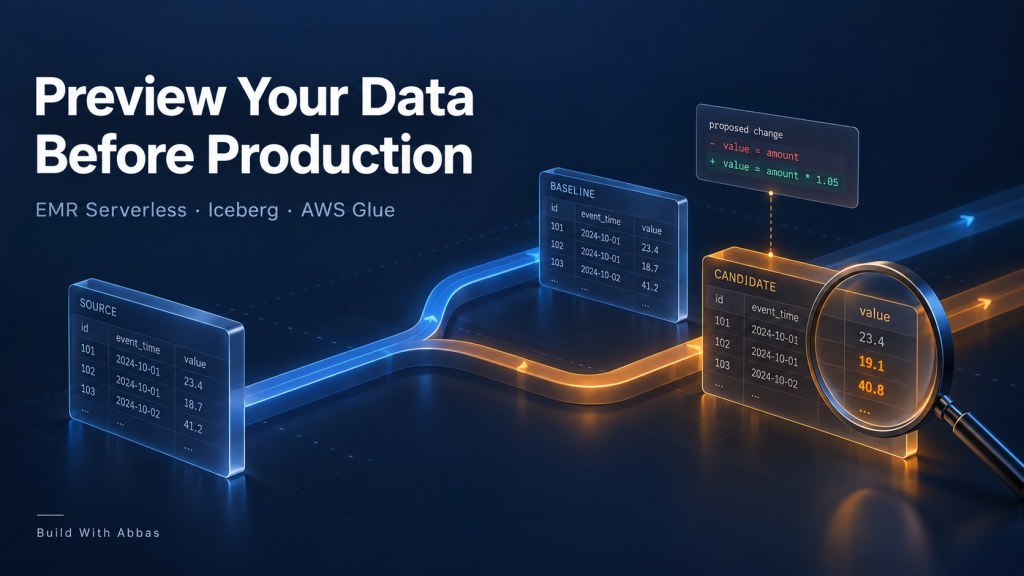
Stop creating table_test: preview your EMR output before you merge
Preview a Spark transformation before production using EMR Serverless, the AWS Glue Data Catalog and Iceberg branches. Run both code versions on pinned input…
-

MCP in Production: Designing the Tool Layer for Enterprise AI Agents on AWS
MCP makes it easier for AI agents to interact with tools, but enterprise production systems require much more than a protocol. This architecture deep…
-

Designing a Production-Grade AI Agent Platform on AWS
A practical architecture review of how to design a production-grade AI agent platform on AWS—starting simple, then adding RAG, vector search, agents, memory, MCP…

